Woocommerce Bulk Product Import Via CSV
A poor WooCommerce CSV can break prices, images or variations. Follow a careful workflow to create, update and check imports. See the steps.
Read the guide →Bulk update Yoast SEO metadata and custom schema across hundreds of WordPress posts using CSV, JSON, SSH, and WP-CLI. Follow this step-by-step guide.
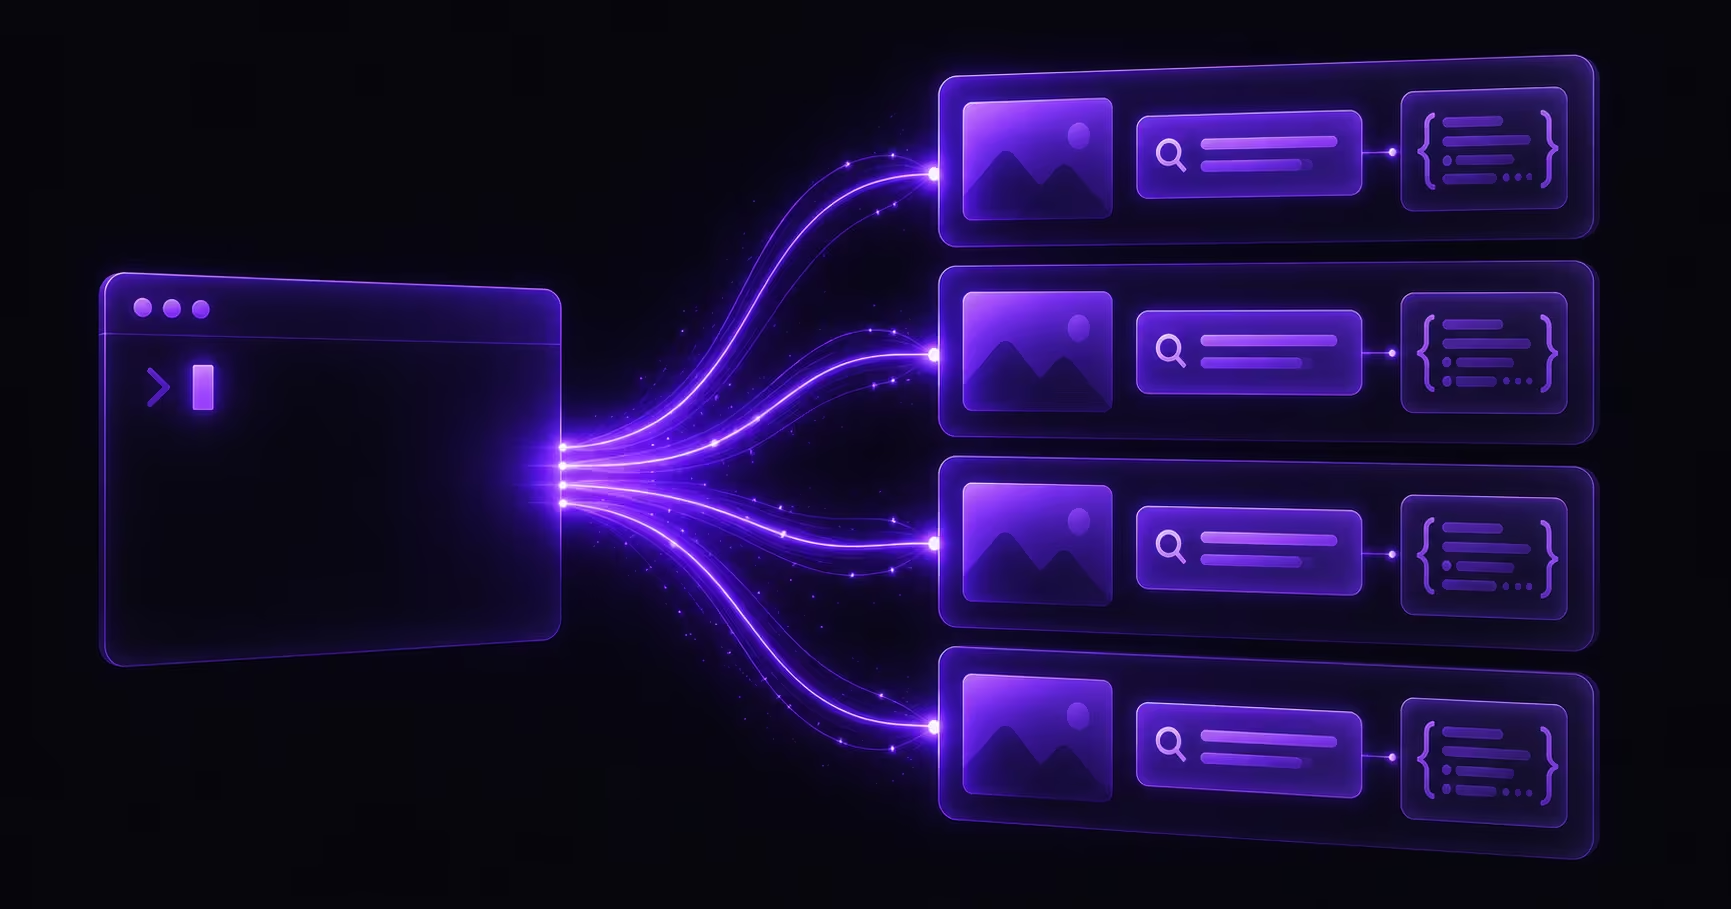
Opening every page and typing the Yoast fields and the schema by hand takes hours. A site with 200 pages takes days, and the schema is the part most people leave out.
There is a faster way. One AI pass writes the metadata CSV, a second writes the schema JSON, and one small script writes both into WordPress over SSH. The script matches pages by URL, so the sitemap you already have is the only inventory you need.
The script runs over SSH, so the host has to allow it first. In Hostinger this lives under the website you are working on, not in the account menu.
ssh -p 12345 u123456789@12.34.567.899yes and press Enter.The port, the username and the IP in that line belong to your server. Never share that line or the password in a screenshot or a chat.
Everything is done from the folder that holds wp-config.php. Type the commands one at a time and read what each ls prints.
ls and press Enter. You should see a folder named domains.cd domains and press Enter.ls again. You now see one folder per website, named after each domain.cd yourdomain.com using your own domain name, then press Enter.ls. You should see public_html.cd public_html and press Enter. This is the WordPress root, the folder with wp-config.php and wp-content.ls once more. Seeing wp-config.php confirms you are in the right folder.ls
cd domains
ls
cd yourdomain.com
cd public_html
lsKeep this terminal window open. The commands in Step 6 run from this folder, and a closed window loses the connection.
A page that is missing from the list keeps its old metadata. A URL that does not exist on the site is reported as NOT FOUND and nothing is written for it.
url, page_type, focus_keyword, meta_title, meta_description, social_title, social_description, canonical_url.Title text %%sep%% %%sitename%%, so the AI never types the site name. Keep the title text under 55 characters and the description under 155.meta-data.csv in UTF-8.Empty cells are ignored. The script never erases a value that already exists.
@graph for that page.No rating, review, price or logo is added unless the page shows one. Schema for something a visitor cannot see is a liability, not a bonus.
If you already have the metadata and the schema in a spreadsheet, a list or another AI answer, skip the writing and use the conversion prompt below. It only formats and checks what you already have.
update-yoast-meta-and-schema.php, meta-data.csv and schema.json into that folder.ls and press Enter. All three files must be listed next to wp-config.php before the next command.lsNow run the preview. It saves nothing.
wp eval-file update-yoast-meta-and-schema.php dry-runRead the lines. WOULD UPDATE lists each page with its title, NOT FOUND means the URL in the CSV or JSON did not match a page, and a warning marks a title over 55 characters or a description over 155. When the list looks right, run the same command without dry-run.
wp eval-file update-yoast-meta-and-schema.phpThe script matches by URL path, not by host, so the same files work on a staging domain and after the move to the live one. Every schema URL and canonical is written with the site’s own home_url().
What it writes: the Yoast focus keyphrase, SEO title, meta description, canonical, Open Graph and Twitter fields, and the custom schema field the plugin reads. It does not touch the content, the post title or the slug. The CSV and the JSON are separate, so you can run the script with only one of them.
application/ld+json and test one URL in the Rich Results Test.rm update-yoast-meta-and-schema.php meta-data.csv schema.json.wp from the wrong folder. It only works after cd public_html, or the command reports that WordPress is not installed.Copy the text below, or download the files above.
YOU ARE WRITING YOAST SEO METADATA FOR A WORDPRESS SITE

I will give you:
- the site domain
- the list of page URLs from the sitemap, with the page type
- the content of each page, or a faithful summary of it
- the keywords I want to target, if I have any

Return one CSV file with one row per page.

COLUMNS (exactly these, in this order, with this header row):
url,page_type,focus_keyword,meta_title,meta_description,social_title,social_description,canonical_url

RULES FOR EACH COLUMN

url
- The absolute URL exactly as I gave it, including the trailing slash.
- Never invent, shorten or rename a URL.

page_type
- One of: home, service, product, category, article, case_study, about, contact, policy, plugin.

focus_keyword
- One keyphrase of 2 to 5 words, lowercase.
- Every page gets a different one. One page owns one query.
- It must appear word for word in the meta title, in the page H1 and in the meta description. If the H1 says "in the USA", write the keyphrase with "in the usa" rather than forcing a phrase that does not fit the page.

meta_title
- Format: Title text %%sep%% %%sitename%%
- Use the token exactly as written. Never type the site name yourself.
- Keep the title text under 55 characters, ideally 40 to 45, because the site name is added after the separator.
- Put the focus keyword near the front.
- Use a number or a price only when it appears on the page.

meta_description
- 120 to 155 characters.
- Include the focus keyword word for word.
- Say what the page actually offers or answers.
- End with a plain next step, not hype.
- No quotation marks inside the text.

social_title and social_description
- Identical to the meta title and the meta description.

canonical_url
- Identical to url.

HONESTY RULES
- Write only what the page really contains.
- No invented prices, ratings, reviews, customer counts, guarantees, awards, addresses or contact details.
- No keyword stuffing. If a phrase does not read naturally, rewrite the sentence.

CSV FORMAT
- UTF-8, one page per line, no empty lines, no comments, no HTML, no emoji.
- Quote every value that contains a comma, a double quote or a line break.
- Return the CSV in one code block so I can copy it.

AFTER THE CSV
List any page where:
- the title text is over 55 characters,
- the description is over 155 characters,
- the focus keyword is missing from the title, the H1 or the description,
- or two pages ended up with the same focus keyword.

FILL IN THESE SECTIONS BEFORE YOU SEND THIS PROMPT

MY DOMAIN:
YOURDOMAIN.com

MY SITEMAP URL:
https://YOURDOMAIN.com/sitemap_index.xml

MY PAGES (paste the URL, page type, H1 and content or summary for every page):

MY KEYWORDS (optional):YOU ARE WRITING JSON-LD SCHEMA FOR A WORDPRESS SITE
I will give you the site domain, the page URLs, the content of each page and the real business details. Return one JSON file that covers every page.
FILE FORMAT (use exactly this shape)
{
"site": "Business name",
"domain": "https://YOURDOMAIN.com",
"notes": "one short paragraph on what is marked up and what is deliberately left out",
"sitewide_schema": { "@context": "https://schema.org", "@graph": [ ] },
"pages": [
{
"url": "https://YOURDOMAIN.com/page/",
"page_type": "service",
"schema": { "@context": "https://schema.org", "@graph": [ ] }
}
]
}
RULES FOR THE FILE
- One entry in "pages" for every URL I give you, in the same order I give them.
- The url value is the absolute URL, trailing slash included, and it must match my list exactly.
- page_type uses the same value as the CSV: home, service, product, category, article, case_study, about, contact, policy, plugin.
- schema is a normal JSON-LD object with "@context": "https://schema.org". Use one "@graph" array per page.
- No script tags, no comments, no trailing commas. Valid JSON only.
WHAT EVERY PAGE GRAPH NEEDS
- A WebSite node: "@id": "https://YOURDOMAIN.com/#website", url, name, inLanguage, and publisher pointing to the organization "@id".
- An Organization node: the type that matches the business (Organization, OnlineStore, ProfessionalService, LocalBusiness). Use only what I give you: name, url, email, telephone, area served. No logo, no sameAs, no address unless I supply them.
- One page node: WebPage, AboutPage, ContactPage, CollectionPage or ItemPage, with url, name, description, isPartOf, inLanguage and a breadcrumb reference.
- A BreadcrumbList on every page except the home page: Home, then the page.
- Connect the nodes with "@id" references so each reference resolves inside the same graph.
PAGE TYPE NODES
- service: a Service node with serviceType, description, provider, areaServed, termsOfService and an Offer with the real starting price and currency, only when the page shows that price.
- product: a Product node with name, description and offers, using only the real price and availability shown on the page.
- article: a BlogPosting or Article with headline, description, url, mainEntityOfPage, author and publisher. Leave dates out; the script adds the real publish and modified dates from WordPress.
- about: an AboutPage whose mainEntity points to the organization.
- contact: a ContactPage whose mainEntity is the organization, with a ContactPoint holding the real email, phone and language.
- policy: a WebPage with dateModified only if the page shows an update date.
- home: a WebPage plus an ItemList of the main services or pages, if the home page links to them.
FAQ RULES
- Add a FAQPage only when the page shows a visible FAQ section.
- Copy the question and the answer word for word from the page. One entry per visible question.
- No FAQ on the page, no FAQPage in the JSON.
HONESTY AND VALIDITY RULES
- Never invent a rating, review, aggregateRating, reviewCount, price, award, credential, address or image URL. If the page does not show it, leave it out.
- Use the real domain everywhere. Never a staging host, never a localhost address.
- Every "@id" reference must point to a node that exists in the same graph.
- Keep url values identical to the CSV and to my sitemap.
AFTER THE JSON
Confirm:
- how many pages are in the file,
- that every URL from my list appears once and none is repeated,
- that the JSON parses,
- which pages have a FAQPage and which do not.
FILL IN THESE SECTIONS BEFORE YOU SEND THIS PROMPT
MY DOMAIN:
YOURDOMAIN.com
MY BUSINESS DETAILS (only the real ones):
- Business name:
- Email:
- Phone:
- Area served:
- Any other fact that appears on the site:
MY PAGES (paste the URL, page type, H1 and content or summary for every page):YOU ARE CONVERTING EXISTING SEO DATA INTO TWO IMPORT FILES
I already have metadata and schema in another form: a spreadsheet, a list, a
previous AI answer, or schema copied from another site. Convert it into the two
files my import script expects. Do not write new SEO copy and do not invent
anything. Format, check and fill gaps only where I tell you to.
FILE 1: meta-data.csv
Header row, exactly these eight columns in this order:
url,page_type,focus_keyword,meta_title,meta_description,social_title,social_description,canonical_url
- url: the absolute URL of the page, trailing slash included. Convert any
relative path such as /about/ into a full URL with my domain.
- page_type: home, service, product, category, article, case_study, about,
contact, policy or plugin.
- focus_keyword: keep the one I gave you. If a row has none, leave it empty
rather than guessing.
- meta_title: keep my title, in the form Title text %%sep%% %%sitename%%.
Remove any site name I typed inside the title, because the %%sitename%%
token adds it. Keep the title text under 55 characters.
- meta_description: keep my description, trimmed to 155 characters or less
without cutting a word in half.
- social_title and social_description: copy the meta title and meta description
unless I gave you different social text.
- canonical_url: copy the url value.
- One row per page, no empty lines. Quote any value that contains a comma, a
quote or a line break. UTF-8.
FILE 2: schema.json
{
"site": "Business name",
"domain": "https://YOURDOMAIN.com",
"notes": "one line describing the source of this data",
"sitewide_schema": { "@context": "https://schema.org", "@graph": [ ] },
"pages": [
{
"url": "https://YOURDOMAIN.com/page/",
"page_type": "service",
"schema": { "@context": "https://schema.org", "@graph": [ ] }
}
]
}
- One entry in "pages" for every URL in the CSV, in the same order.
- Copy the schema I give you into "schema". Remove any script tags around it
and keep it as a JSON object, not a string.
- If my schema is a single object, put it inside "@graph": [ ... ] and set
"@context": "https://schema.org" at the top of that page.
- Convert every relative URL to the absolute URL with my domain.
- If a node points to another node by "@id", keep the reference only when that
node exists in the same page graph. Otherwise remove the reference.
- Do not add ratings, reviews, prices, images, logos or social profiles that
were not in my data.
- Valid JSON only: no comments, no trailing commas, no script tags.
CHECKS BEFORE YOU ANSWER
- Every CSV url appears once in schema.json, and every schema url appears once
in the CSV.
- No value contains a raw line break.
- The JSON parses.
OUTPUT
- Two code blocks: first the CSV, then the JSON.
- After them, list what you changed, which rows were missing data, and which
URLs were dropped because they did not match.
MY DOMAIN:
YOURDOMAIN.com
MY EXISTING DATA (paste the spreadsheet, list, AI answer or schema below):<?php
/**
* update-yoast-meta-and-schema.php
*
* Fills the Yoast SEO fields and the custom schema of the
* "Schema & Structured Data for WP & AMP" plugin for EXISTING pages, posts or
* products, using two files: meta-data.csv and schema.json.
* Pages are matched by URL path, so the same files work on a staging domain
* and after the site moves to its live domain. Nothing is created or deleted.
* Content, titles and slugs are not touched.
*
* FILES (keep all three in one folder):
* update-yoast-meta-and-schema.php this script
* meta-data.csv Yoast fields, one row per page
* schema.json JSON-LD, one entry per page (optional)
*
* CSV COLUMNS (header row required):
* url, focus_keyword, meta_title, meta_description,
* canonical_url, social_title, social_description
* Only url is required. Empty cells are ignored, so existing values are kept.
*
* USAGE (WP-CLI over SSH, from the folder that holds wp-config.php):
* # 1. Preview. Saves nothing:
* wp eval-file update-yoast-meta-and-schema.php dry-run
*
* # 2. If the preview looks right, run it for real:
* wp eval-file update-yoast-meta-and-schema.php
*
* # Optional: pass the folder that holds the two data files:
* wp eval-file update-yoast-meta-and-schema.php /path/to/folder dry-run
*
* BEFORE YOU RUN IT
* In the schema plugin, create a schema of type "Custom Schema" and set it
* to show on the pages you are importing (Structured Data > Add Schema Type).
* Without that, the plugin stores the schema but does not print it.
*/
if ( ! defined( 'WP_CLI' ) || ! WP_CLI ) {
fwrite( STDERR, "This file must be run with WP-CLI: wp eval-file update-yoast-meta-and-schema.php\n" );
return;
}
/*
* Where the plugin keeps the per-page custom schema. If your version of the
* plugin uses a different meta key, save a test schema on one page, run
* "wp post meta list POST_ID", and change this value.
*/
$meta_key = 'saswp_custom_schema_field';
/* Set to true only if the plugin needs the schema wrapped in script tags. */
$wrap_in_script = false;
$args = isset( $args ) && is_array( $args ) ? $args : array();
$dry_run = in_array( 'dry-run', $args, true );
/* -------------------------------------------------------------------------
* Find the data files.
* ---------------------------------------------------------------------- */
$search_dirs = array();
foreach ( $args as $arg ) {
if ( is_string( $arg ) && is_dir( $arg ) ) {
$search_dirs[] = rtrim( $arg, '/\\' );
}
}
$search_dirs[] = __DIR__;
$search_dirs[] = getcwd();
$search_dirs[] = getcwd() . '/seo-import';
$data_dir = '';
foreach ( array_unique( $search_dirs ) as $candidate ) {
if ( file_exists( $candidate . '/meta-data.csv' ) || file_exists( $candidate . '/schema.json' ) ) {
$data_dir = $candidate;
break;
}
}
if ( '' === $data_dir ) {
WP_CLI::error( 'meta-data.csv and schema.json were not found. Put this script next to both files, or pass the folder as the first argument.' );
}
$csv_path = $data_dir . '/meta-data.csv';
$json_path = $data_dir . '/schema.json';
/* -------------------------------------------------------------------------
* Read the CSV.
* ---------------------------------------------------------------------- */
$rows = array();
if ( file_exists( $csv_path ) ) {
$handle = fopen( $csv_path, 'r' );
if ( ! $handle ) {
WP_CLI::error( 'Could not open ' . $csv_path );
}
$headers = fgetcsv( $handle, 0, ',', '"', '' );
if ( ! $headers ) {
WP_CLI::error( 'meta-data.csv is empty.' );
}
$headers[0] = preg_replace( '/^\xEF\xBB\xBF/', '', $headers[0] );
$headers = array_map(
function ( $h ) {
return strtolower( trim( $h ) );
},
$headers
);
if ( ! in_array( 'url', $headers, true ) ) {
WP_CLI::error( 'meta-data.csv needs a url column in the first row.' );
}
while ( ( $line = fgetcsv( $handle, 0, ',', '"', '' ) ) !== false ) {
if ( array( null ) === $line || ( 1 === count( $line ) && '' === trim( (string) $line[0] ) ) ) {
continue;
}
if ( count( $line ) !== count( $headers ) ) {
WP_CLI::warning( 'Skipped a CSV row with the wrong number of columns: ' . implode( ' | ', array_slice( $line, 0, 3 ) ) );
continue;
}
$row = array_combine( $headers, $line );
if ( empty( $row['url'] ) ) {
continue;
}
$rows[ trim( $row['url'] ) ] = $row;
}
fclose( $handle );
}
/* -------------------------------------------------------------------------
* Read the schema JSON.
* ---------------------------------------------------------------------- */
$schemas = array();
$source_domain = '';
if ( file_exists( $json_path ) ) {
$payload = json_decode( (string) file_get_contents( $json_path ), true );
if ( ! is_array( $payload ) ) {
WP_CLI::error( 'schema.json is not valid JSON: ' . json_last_error_msg() );
}
if ( ! empty( $payload['pages'] ) && is_array( $payload['pages'] ) ) {
foreach ( $payload['pages'] as $page ) {
if ( ! empty( $page['url'] ) && ! empty( $page['schema'] ) ) {
$schemas[ $page['url'] ] = $page['schema'];
}
}
} elseif ( isset( $payload[0]['url'] ) ) {
// A plain list is accepted too.
foreach ( $payload as $page ) {
if ( ! empty( $page['url'] ) && ! empty( $page['schema'] ) ) {
$schemas[ $page['url'] ] = $page['schema'];
}
}
}
if ( ! empty( $payload['domain'] ) ) {
$source_domain = rtrim( $payload['domain'], '/' );
}
}
if ( ! $rows && ! $schemas ) {
WP_CLI::error( 'No usable data found. meta-data.csv needs a url column, or schema.json needs a pages list.' );
}
$target_domain = untrailingslashit( home_url( '/' ) );
if ( '' === $source_domain ) {
$source_domain = $target_domain;
}
/* -------------------------------------------------------------------------
* Helpers.
* ---------------------------------------------------------------------- */
function yaas_swap_domain( $value, $source, $target ) {
if ( is_array( $value ) ) {
foreach ( $value as $key => $item ) {
$value[ $key ] = yaas_swap_domain( $item, $source, $target );
}
return $value;
}
if ( is_string( $value ) && '' !== $source ) {
return str_replace( $source, $target, $value );
}
return $value;
}
function yaas_find_post_id( $url ) {
$path = parse_url( $url, PHP_URL_PATH );
$path = $path ? $path : '/';
$home_path = parse_url( home_url( '/' ), PHP_URL_PATH );
$home_path = $home_path ? untrailingslashit( $home_path ) : '';
if ( '' !== $home_path && 0 === strpos( $path, $home_path ) ) {
$path = substr( $path, strlen( $home_path ) );
}
$path = '/' . ltrim( $path, '/' );
if ( '/' === $path ) {
$front = (int) get_option( 'page_on_front' );
if ( $front > 0 ) {
return $front;
}
$home = get_page_by_path( 'home' );
return $home ? (int) $home->ID : 0;
}
$post_id = url_to_postid( home_url( $path ) );
if ( ! $post_id ) {
$post_id = url_to_postid( home_url( untrailingslashit( $path ) . '/' ) );
}
if ( ! $post_id ) {
$slug = basename( untrailingslashit( $path ) );
$found = get_posts(
array(
'name' => $slug,
'post_type' => 'any',
'post_status' => 'any',
'posts_per_page' => 1,
'fields' => 'ids',
'suppress_filters' => true,
)
);
if ( $found ) {
$post_id = (int) $found[0];
}
}
return (int) $post_id;
}
function yaas_add_dates( &$schema, $post ) {
if ( empty( $schema['@graph'] ) || ! is_array( $schema['@graph'] ) ) {
return;
}
$published = get_post_time( 'c', true, $post );
$modified = get_post_modified_time( 'c', true, $post );
$image = get_the_post_thumbnail_url( $post, 'full' );
foreach ( $schema['@graph'] as &$node ) {
if ( ! is_array( $node ) || empty( $node['@type'] ) ) {
continue;
}
$types = (array) $node['@type'];
if ( ! array_intersect( $types, array( 'BlogPosting', 'Article', 'NewsArticle' ) ) ) {
continue;
}
if ( empty( $node['datePublished'] ) && $published ) {
$node['datePublished'] = $published;
}
if ( empty( $node['dateModified'] ) && $modified ) {
$node['dateModified'] = $modified;
}
if ( empty( $node['image'] ) && $image ) {
$node['image'] = $image;
}
}
unset( $node );
}
/* -------------------------------------------------------------------------
* Import.
* ---------------------------------------------------------------------- */
if ( ! defined( 'WPSEO_VERSION' ) ) {
WP_CLI::warning( 'Yoast SEO does not look active. The Yoast meta is still saved and will show once Yoast is active.' );
}
if ( ! post_type_exists( 'saswp' ) ) {
WP_CLI::warning( 'Schema & Structured Data for WP does not look active. The schema is still saved and will print once the plugin is active.' );
}
$field_map = array(
'focus_keyword' => '_yoast_wpseo_focuskw',
'meta_title' => '_yoast_wpseo_title',
'meta_description' => '_yoast_wpseo_metadesc',
'canonical_url' => '_yoast_wpseo_canonical',
'social_title' => '_yoast_wpseo_opengraph-title',
'social_description' => '_yoast_wpseo_opengraph-description',
);
$urls = array_keys( $rows );
foreach ( array_keys( $schemas ) as $schema_url ) {
if ( ! in_array( $schema_url, $urls, true ) ) {
$urls[] = $schema_url;
}
}
WP_CLI::log( 'Data folder: ' . $data_dir );
WP_CLI::log( 'Site: ' . $target_domain );
WP_CLI::log( 'Pages in CSV: ' . count( $rows ) . ' | pages in JSON: ' . count( $schemas ) );
WP_CLI::log( $dry_run ? 'Mode: dry run (nothing will be saved)' : 'Mode: live import' );
$updated = 0;
$not_found = 0;
$no_schema = 0;
$skipped = 0;
foreach ( $urls as $url ) {
$post_id = yaas_find_post_id( $url );
if ( ! $post_id || ! get_post( $post_id ) ) {
WP_CLI::warning( 'NOT FOUND: ' . $url );
$not_found++;
continue;
}
$row = isset( $rows[ $url ] ) ? $rows[ $url ] : array();
$meta = array();
foreach ( $field_map as $column => $key ) {
if ( ! isset( $row[ $column ] ) ) {
continue;
}
$value = trim( (string) $row[ $column ] );
if ( '' === $value ) {
continue;
}
$meta[ $key ] = yaas_swap_domain( $value, $source_domain, $target_domain );
}
// Twitter cards mirror the Open Graph values.
if ( isset( $meta['_yoast_wpseo_opengraph-title'] ) ) {
$meta['_yoast_wpseo_twitter-title'] = $meta['_yoast_wpseo_opengraph-title'];
}
if ( isset( $meta['_yoast_wpseo_opengraph-description'] ) ) {
$meta['_yoast_wpseo_twitter-description'] = $meta['_yoast_wpseo_opengraph-description'];
}
$schema_json = '';
if ( isset( $schemas[ $url ] ) ) {
$schema = yaas_swap_domain( $schemas[ $url ], $source_domain, $target_domain );
yaas_add_dates( $schema, get_post( $post_id ) );
$schema_json = wp_json_encode( $schema, JSON_UNESCAPED_SLASHES | JSON_UNESCAPED_UNICODE | JSON_PRETTY_PRINT );
if ( false === $schema_json ) {
WP_CLI::warning( 'Could not encode the schema for ' . $url . '; skipped it.' );
$schema_json = '';
}
if ( $wrap_in_script ) {
$schema_json = '<script type="application/ld+json">' . $schema_json . '</script>';
}
} else {
$no_schema++;
}
if ( ! $meta && '' === $schema_json ) {
$skipped++;
continue;
}
if ( $dry_run ) {
WP_CLI::log( sprintf( 'WOULD UPDATE #%d %s', $post_id, $url ) );
if ( isset( $meta['_yoast_wpseo_title'] ) ) {
$plain = str_replace( array( ' %%sep%% %%sitename%%', '%%sep%%' ), '', $meta['_yoast_wpseo_title'] );
$note = mb_strlen( $plain ) > 55 ? ' <-- title text over 55 characters' : '';
WP_CLI::log( ' title (' . mb_strlen( $plain ) . '): ' . $plain . $note );
}
if ( isset( $meta['_yoast_wpseo_metadesc'] ) ) {
$note = mb_strlen( $meta['_yoast_wpseo_metadesc'] ) > 155 ? ' <-- over 155 characters' : '';
WP_CLI::log( ' description (' . mb_strlen( $meta['_yoast_wpseo_metadesc'] ) . ')' . $note );
}
if ( '' !== $schema_json ) {
WP_CLI::log( ' schema (' . strlen( $schema_json ) . ' bytes)' );
}
$updated++;
continue;
}
foreach ( $meta as $key => $value ) {
update_post_meta( $post_id, $key, wp_slash( $value ) );
}
if ( '' !== $schema_json ) {
update_post_meta( $post_id, $meta_key, wp_slash( $schema_json ) );
if ( 'saswp_custom_schema_field' === $meta_key ) {
update_post_meta( $post_id, '_saswp_custom_schema_field', wp_slash( $schema_json ) );
}
}
$updated++;
WP_CLI::log( sprintf( 'UPDATED #%d %s', $post_id, $url ) );
}
/* Turn the plugin's custom schema output back on if it was switched off. */
if ( ! $dry_run ) {
$sd_data = get_option( 'sd_data' );
if ( is_array( $sd_data ) && isset( $sd_data['saswp-for-cschema'] ) && '0' === (string) $sd_data['saswp-for-cschema'] ) {
$sd_data['saswp-for-cschema'] = '1';
update_option( 'sd_data', $sd_data );
WP_CLI::log( 'Enabled custom schema output in the plugin settings.' );
}
if ( function_exists( 'wp_cache_flush' ) ) {
wp_cache_flush();
}
}
WP_CLI::success(
sprintf(
'%s %d pages. Not found: %d. Without schema: %d. Nothing to write: %d.',
$dry_run ? 'Dry run complete for' : 'Imported',
$updated,
$not_found,
$no_schema,
$skipped
)
);
if ( $not_found > 0 ) {
WP_CLI::warning( 'Some URLs did not match a page. Check the permalink structure and that every URL in the files exists on this site.' );
}Yoast SEO, Schema & Structured Data for WP & AMP, an AI assistant, sitemap.xml, Hostinger SSH, WP-CLI, one PHP script.
Need this done for you? See my technical SEO service.
A poor WooCommerce CSV can break prices, images or variations. Follow a careful workflow to create, update and check imports. See the steps.
Read the guide →SEO timing depends on your niche and competitors. Learn what affects progress, what to review first and why no exact date is promised. Explore the guide.
Read the guide →